Enterprise AI Compute & Model Orchestration
Hybrid AI Infrastructure & Distributed GPU Orchestration
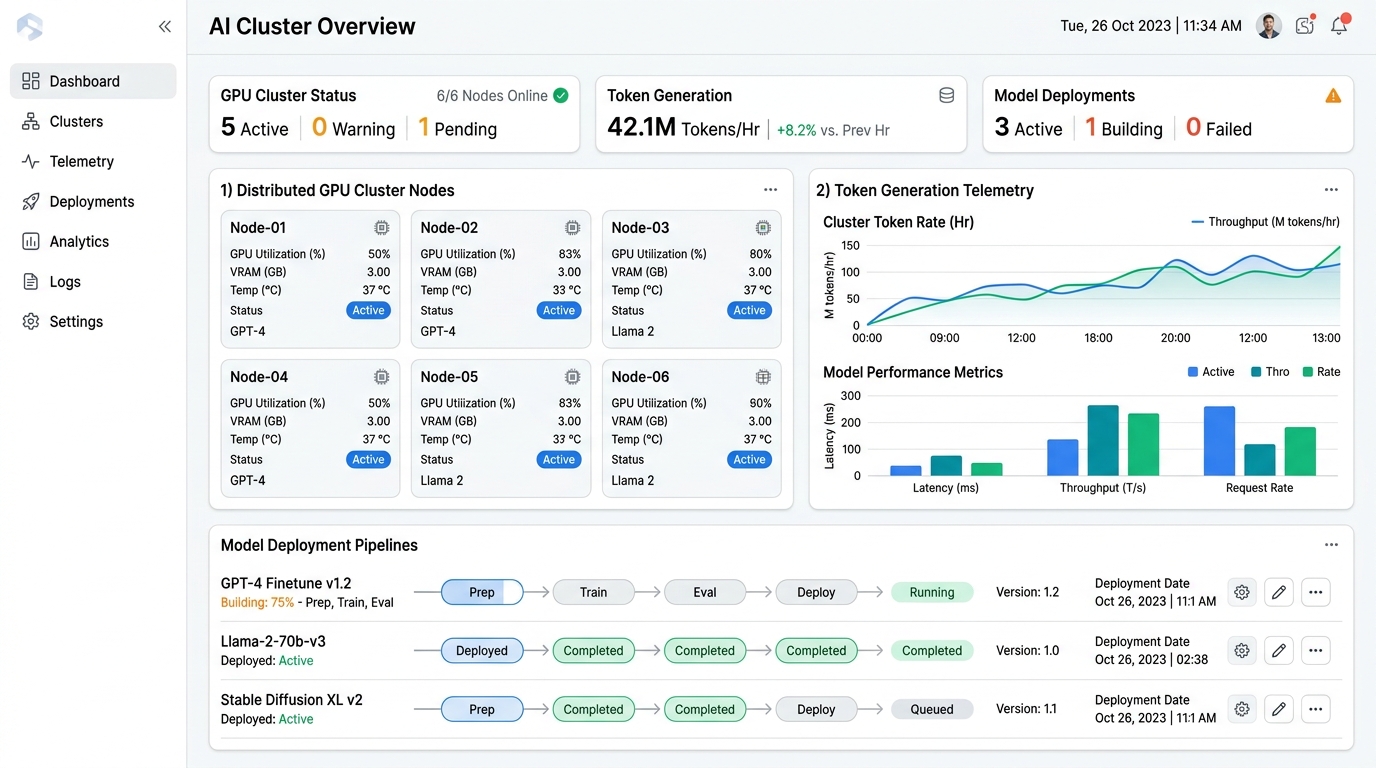
AppZed orchestrates generative AI models across heterogeneous GPU clusters, optimizing token throughput, inference latency, and hardware utilization.
https://appzed.com/preview — AppZed AI Cluster Overview & GPU Telemetry Canvas
Private Beta
Current Release Cycle
Agentic AI
Autonomous Agent Architecture
100%
Data Privacy & Security
Early Access
Design Partner Validation